
Breaking News

GLOBAL Wi-Fi NEWS bulletin

Outdoor autonomous systems require more than just accurate positioning, especially in mission-critical environments. In UAVs, defense applications and remote infrastructure systems, GNSS must continue operating under interference, degraded signals and dynamic conditions, while providing high data confidence.

The Septentrio mosaic-X5 GNSS M.2 receiver module is designed for this class of problem. It combines multi-frequency GNSS tracking with interference mitigation, signal authentication and integrity monitoring. When integrated with Gateworks industrial single board computers, it enables a modular architecture for high-integrity positioning at the edge.

GNSS Performance Beyond Accuracy

The mosaic-X5 is a multi-band, multi-constellation receiver tracking GPS, Galileo, GLONASS, BeiDou and NavIC across multiple frequency bands. Multi-frequency operation improves positioning robustness and reduces susceptibility to ionospheric errors and signal degradation. It supports RTK positioning and update rates up to 100 Hz, allowing it to maintain low-latency tracking for dynamic systems such as UAVs and mobile platforms. These characteristics are essential for maintaining control fidelity in real-world environments.

Assured Positioning, Navigation and Timing (PNT): Anti-Jamming, Anti-Spoofing and Integrity

For defense and mission-critical systems, the key question is not just “how accurate is the position?” but “can the system trust it?”

The mosaic-X5 integrates Septentrio’s AIM+ (Advanced Interference Mitigation) technology, which actively detects and suppresses interference across both narrowband and wideband signals. This includes resilience against pulsed and complex jamming scenarios.
It also incorporates:

  • Anti-spoofing and signal validation to detect anomalous GNSS behavior
  • RAIM+ (Receiver Autonomous Integrity Monitoring) to assess positioning reliability
  • APME+ (Advanced Multipath Mitigation) to reduce reflected signal errors
  • LOCK+ for robustness under shock and vibration
  • OSNMA (Open Service Navigation Message Authentication) supports signal authentication

These capabilities position the mosaic-X5 within the broader concept of assured PNT, maintaining reliable and trustworthy positioning in contested environments.

RTK Correction Services and Scalable Deployment

High-precision positioning depends on correction data. The mosaic-X5 supports standard methods such as NTRIP as well as satellite-delivered corrections.

Services like u-blox PointPerfect GNSS correction service provide PPP-RTK corrections over IP or L-band, enabling centimeter-level positioning without requiring local base stations. This model simplifies deployment for distributed systems and mobile fleets.
For example:

  • Cellular-connected systems can stream corrections via NTRIP
  • Remote systems can use satellite-delivered corrections
  • Private networks can deploy local base stations

This flexibility allows system designers to align correction strategies with operational constraints.

UAV and Defense System Relevance

Unmanned and defense systems operate in environments where GNSS degradation is expected, not exceptional. Positioning systems must maintain accuracy, continuity and integrity under these conditions. The GW16160 Mosaic x5 M.2 is industrial grade and engineered to perform in -40°C to +85°C temperatures and extreme environments.
The mosaic-X5 supports:

  • Autonomous navigation and waypoint execution
  • Geofencing and mission planning
  • Mapping, inspection and situational awareness

It is also included in the Blue UAS Framework, a program led by the U.S. Department of Defense to identify trusted components for unmanned systems. This reflects both technical capability and supply chain trust, two critical requirements for defense deployments.

Practical Integration: GW16160 and Gateworks Platforms

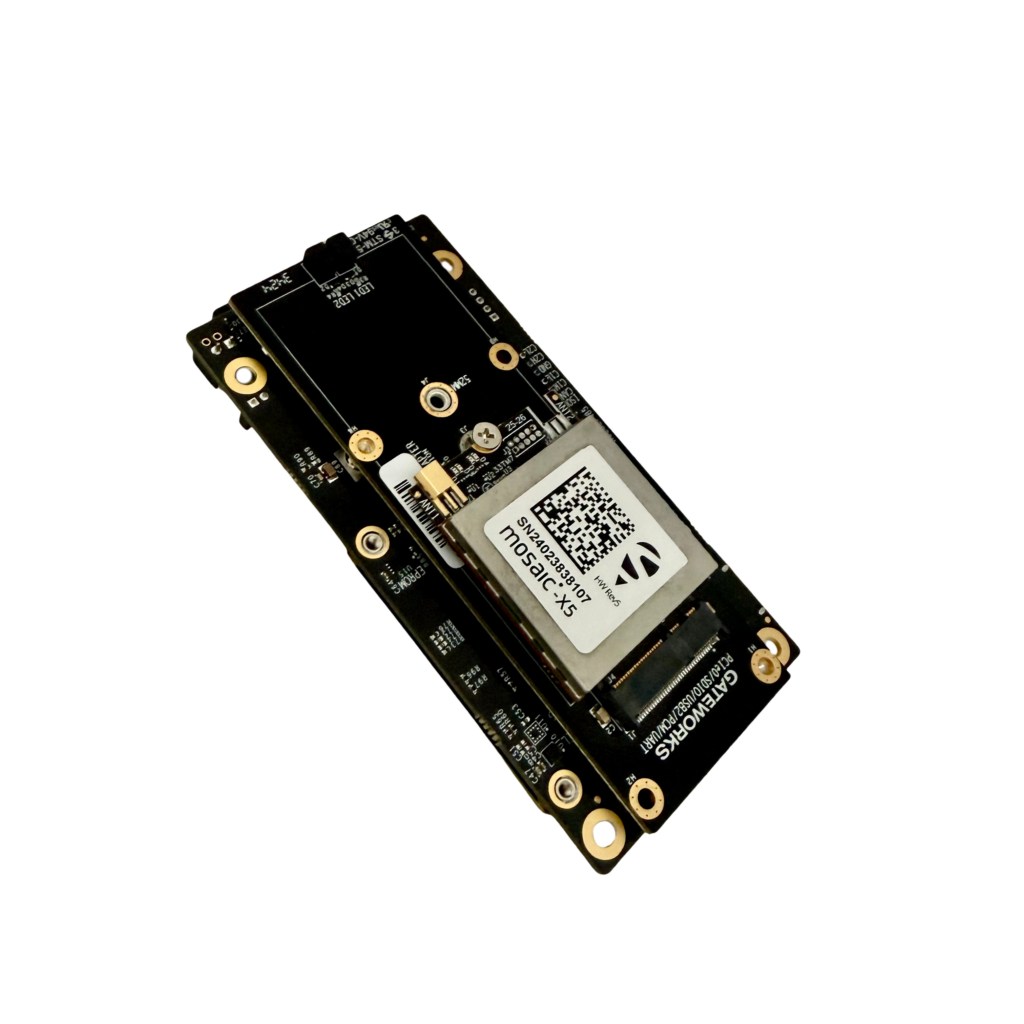
The Gateworks GW16160 GNSS M.2 module integrates the mosaic-X5 into a compact, deployable form factor. It provides a plug-and-play GNSS solution for Gateworks SBCs using a standard M.2 interface.

This reduces:

  • Custom hardware design effort
  • Integration complexity
  • Time to deployment

GW16160 pictured with the GW8100 VeniceFLEX

The GW16160 is for use in autonomous systems, robotics, drones and outdoor asset tracking, where reliable GNSS is a foundational capability.

Gateworks platforms provide the compute and connectivity layer:

The NXP i.MX95 application processor enables AI-accelerated processing, advanced security and real-time system integration, supporting GNSS as one component within a broader autonomy stack.

Security, Traceability and Manufacturing Considerations

For defense and infrastructure deployments, hardware selection includes more than performance; it includes traceability, security and lifecycle control.

We design and manufacture all of our products in the United States, with a vertically integrated production process that emphasizes:

  • Full component traceability
  • Controlled manufacturing workflows
  • Long lifecycle availability

Gateworks products are assembled, tested and tracked within a single facility, with serialized components and real-time process visibility. These factors support deployments where supply chain transparency and long-term support are required. https://www.gateworks.com/company/manufacturing/

System-Level Architecture

In practice, GNSS is one part of a larger system:

  • GNSS receiver (mosaic-X5)
  • Correction service (e.g., u-blox PointPerfect GNSS correction service, NTRIP, etc.)
  • Embedded compute (Gateworks Venice, VeniceFLEX, Catalina)
  • Connectivity (cellular, Wi-Fi HaLow, Wi-Fi)

This modular architecture allows systems to scale across deployment environments while maintaining positioning performance and system flexibility.

Conclusion

For mission-critical outdoor systems, GNSS must deliver more than accuracy; it must deliver resilience, integrity and trust.

The mosaic-X5 addresses these requirements through multi-frequency tracking, interference mitigation, anti-spoofing and integrity monitoring. Gateworks single board computers combined with the GW16160 module allow for a practical path to deploying high-integrity positioning within embedded edge systems.

This approach aligns with the needs of modern autonomous and defense systems, where positioning is not just an input but a trusted foundation for decision-making.

Modernizing RF exposure management

Qualcomm’s engineering journey to evolve RF exposure management for modern wireless performance

What you should know:
  • Time-Averaged Specific Absorption Rate (TAS), is a method of RF exposure management established by Qualcomm Technologies to address evolving performance requirements of 5G, multi-radio devices and emerging technologies while meeting worldwide RF exposure regulation. 
  • Between 2012 and 2019, Qualcomm led the industry in research, testing and validation, culminating in a breakthrough solution that set a new standard for the industry. 
  • Our innovations paved the way for other OEMs and set new benchmarks for compliance and performance, and transformed how the industry approaches RF exposure compliance and device performance.

When Qualcomm Technologies pioneered a new way to manage RF exposure through real-time averaging, it wasn’t simply about a new product. Behind this breakthrough development is a story about years of vision, collaboration and technical rigor that paved the way for a new era in RF exposure management. Spanning nearly a decade, the journey to develop this new technology — Time-Averaged Specific Absorption Rate (SAR), also known as TAS — stands as another example of our relentless drive to develop the best wireless experience possible and deliver maximum benefit to industry and consumers.

A foundation built on determination: 2012–2019

Developing TAS required years of systematic effort to redefine how wireless devices manage RF exposure. Our expertise in mobile gave us a unique line of sight to where the industry was headed, and we were pursuing novel ways to enable the growth required for better uplink performance.

The seeds of TAS were planted in 2012, when our engineers and scientists recognized a looming challenge: Legacy RF exposure management was holding back the promise of next-generation wireless technologies. The team saw that RF exposure management using static, capped peak power limits were stifling innovation and making it harder for device makers to deliver the performance users were demanding. Thus began a decade of dialog, research, testing and validation, culminating in a breakthrough solution that set a new standard for the industry.

This effort unfolded through several key milestones:

  • Early regulatory engagement:

In 2012, we presented the concept of real-time averaging for RF exposure management to the FCC, initiating a dialogue that would shape future compliance procedures. We worked closely with regulators worldwide, advocating for the adoption of time averaging as a scientifically sound and practical approach to Regulatory compliance.

  • Technical prototyping and validation:

Between 2013 and 2015, Qualcomm Technologies developed and tested prototype algorithms and devices, including the first sub-6 GHz hand-held device. These efforts demonstrated the feasibility of real-time power averaging and provided critical data for regulatory review.

  • Establishment of new regulatory test procedures:

In 2016, we released to the regulators the first version of SAR measurement procedures for validating TAS algorithms. Since then, the test cases and procedures for regulatory certification of wireless devices enabled with TAS RF exposure management have been updated to validate enhancements and used to enable other TAS providers to enter the market.

  • Algorithm development for 5G and mmWave:

As wireless technology has evolved, so have Qualcomm Technologies’ solutions. In 2018, our engineers expanded the algorithms to support 5G mmWave, addressing new challenges in device complexity and simultaneous multi-radio transmissions.

  • Collaboration with third-party labs:

To ensure robust validation, Qualcomm Technologies partnered with leading compliance labs and third-party test houses worldwide. These collaborations helped to harmonize TAS testing procedures and meet the compliance test and regulatory certification needs of OEMs for on-time launch of their commercial products.

  • Regulatory approval:

In 2018, the FCC first approved time averaging procedures for sub-6 GHz and mmWave devices, a direct result of our sustained engagement and technical advocacy. This enabled OEMs to design for compliance using time averaging, rather than relying on legacy power back-off methods.

  • Industry education and knowledge transfer:

Qualcomm invested significant resources in educating OEMs, operators, and labs about the new approach. Our teams provide training, consulting and technical support to accelerate industry adoption and ensure consistent, reliable compliance. To date, we have on-boarded 25 compliance labs in 8 different countries with 10 more labs in progress.

The launch: Qualcomm Smart Transmit becomes reality

In April 2019, Qualcomm Technologies launched TAS as a commercial product, branded Smart Transmit, as an optional feature in the first 5G-enabled smartphones. Smart Transmit was more than a product introduction; it was the culmination of years of hard work, technical excellence and industry-wide collaboration. The technology was validated, the ecosystem was ready and the industry was aligned on the benefits of dynamic RF exposure management.

Why this journey matters

In addition to cellular, today Smart Transmit includes Wi-Fi, Bluetooth® wireless technology, UWB, RFID and satellite radios. The rise of AI, XR and an ever-increasing number of wearables are placing even more importance on the efficiency and capacity of uplink transmission as devices send more and more data to the cloud for real-time learning and personalization.

The principles and methodologies developed during this journey paved the way for other OEMs and set new benchmarks for compliance and performance. The groundwork laid between 2012 and 2019 enabled not just a technical solution, but a transformation in how the industry approaches RF exposure compliance and device performance.

Qualcomm’s leadership in developing TAS reflects the strength of our research and development teams, our engineering ingenuity and our commitment to solving the hardest problems in wireless.

The core mission of electronic warfare (EW) hasn’t changed: control the all communications so your forces can operate, and your adversary cannot. What has changed is everything around it. Today’s EW systems operate across airborne, naval and ground platforms that are increasingly built around multifunction RF architectures, where radar, sensing and electronic support capabilities are integrated into a single system.

In addition, performance expectations continue to rise. As threats appear without warning and signals shift instantly, response time is no longer measured in seconds, but in microseconds. Systems must continuously sense, interpret and respond across the entire RF spectrum.

EW environments now require wide instantaneous bandwidth, high output power and stable operation under extreme conditions. Publicly acknowledged frequency ranges such as 6–18 GHz and 32–38 GHz highlight the breadth of spectrum these systems must cover, often extending even further in practice.

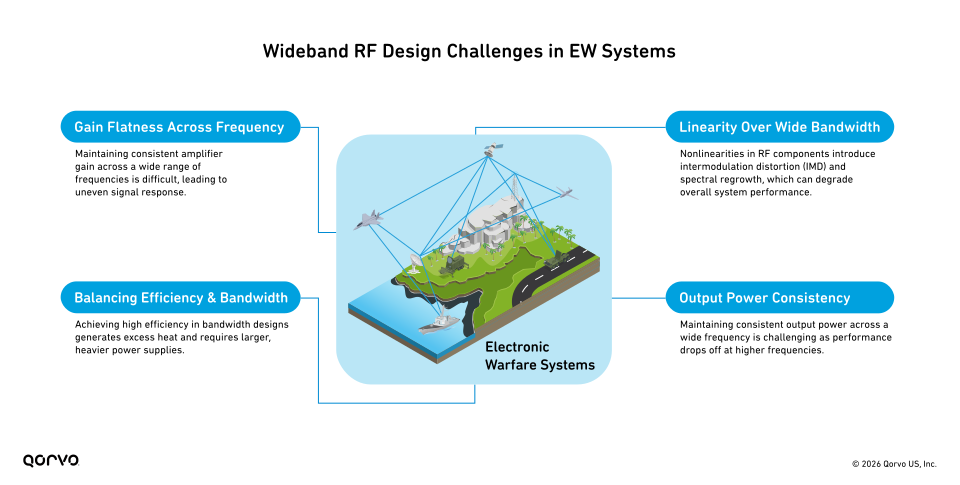
Wideband RF Design Challenges in EW Systems

Wideband EW design comes with distinct design challenges because of the need to make one RF chain behave well everywhere, all at once, across frequency, power levels and operating conditions.

EW receivers are designed to achieve high spurious-free dynamic range (SFDR), typically in the 90–110 dB range, enabling detection of weak signals in the presence of strong interferers. For example, a 6–18 GHz receiver with 500 MHz bandwidth and a ~5 dB noise figure yields a noise floor near −82 dBm, with minimum detectable signals around −72 dBm when accounting for detection margin. To meet these requirements, wideband low-noise amplifiers must maintain 2–3 dB Noise Figures with minimal Gain variation, while also delivering high linearity, often with Third-order Intercept Points near +30 dBm and compression points around +20 dBm, requiring careful matching, biasing and thermal design.

Here are the core challenges engineers must solve:

Gain Flatness Across Frequency

Maintaining Gain flatness across frequency is a key challenge in wideband EW design. Amplifiers inherently exhibit Gain variation over frequency, which becomes more pronounced as bandwidth increases, leading to uneven signal response and potential distortion. Addressing this requires carefully engineered matching networks and equalization techniques to stabilize performance across the operating range. In EW systems, inconsistent Gain can degrade signal fidelity, resulting in missed detections or reduced jamming effectiveness.

Linearity Over Wide Bandwidth

Maintaining linearity over wide bandwidths is another critical challenge in EW system design. Wideband signals often contain multiple simultaneous tones and complex modulations, increasing the likelihood of nonlinear behavior in RF components. This nonlinearity generates intermodulation distortion (IMD) and spectral regrowth, which can degrade overall system performance. In practice, distortion can mask weak signals, reduce the effectiveness of jamming operations and even interfere with friendly systems operating within the same spectral environment.

Efficiency vs. Bandwidth Tradeoffs

Balancing efficiency and bandwidth is a fundamental tradeoff in EW system design. High efficiency is typically easier to achieve in narrowband architectures, where components can be optimized for a specific frequency range. In contrast, wideband systems often sacrifice efficiency to maintain performance across a broader spectrum. This reduced efficiency leads to increased heat generation, larger power supply requirements and degraded size, weight and power (SWaP) performance, factors that directly impact system integration and operational effectiveness.

Output Power Consistency

Maintaining consistent output power across a wide frequency range is a significant challenge in EW system design. As frequency increases, device performance often begins to degrade, making it difficult to sustain high power levels across the entire operating band. This variability can impact overall system effectiveness, particularly in jamming applications where consistent power delivery across the spectrum is essential to ensure reliable threat suppression.

Wideband RF Design Challenges in Modern EW Systems
Wideband RF design in electronic warfare systems requires balancing gain, linearity, efficiency and output power across a broad, dynamic spectrum that will ensure consistent, reliable performance in real-time, mission-critical environments.

How to Address Wideband EW Challenges

Wideband EW architectures address core RF design challenges through a combination of solid-state technologies, optimized circuit design and system-level integration. Solid-state power amplifiers and carefully engineered RF front ends enable more predictable gain behavior across wide frequency ranges, while optimized matching networks and equalization techniques help minimize variation and ensure uniform signal amplification, which reduces the risk of missed detections or degraded jamming effectiveness. The inherent predictability of these devices also supports improved linearity, and when paired with optimized biasing and system-level design, helps reduce intermodulation distortion and spectral regrowth to preserve signal integrity in dense, multi-signal environments.

At the same time, solid-state solutions help manage the tradeoffs between efficiency and bandwidth by delivering improved Power-Added Efficiency (PAE) and more consistent performance across temperature and load conditions, reducing excess heat and supporting more SWaP-efficient designs. These architectures also enable more consistent output power across wide frequency ranges, particularly when implemented in modular form factors that allow power scaling without redesigning the entire transmit chain. On the receive side, wideband low-noise amplifiers and front-end limiters protect sensitive components while maintaining stable noise figure and gain, preserving detection capability across the spectrum. Finally, integrated RF modules simplify system design, reduce assembly complexity and improve repeatability, while the inherent reliability of solid-state architectures ensures consistent performance under sustained, mission-critical operating conditions.

Conclusion

Wideband EW design is a constant balancing act—maintaining gain, linearity, efficiency and stability across a broad and dynamic spectrum, often under high power and real-time operational constraints.

By aligning device technology, integration strategy and system design with the realities of wideband operation, engineers can overcome the core challenges of modern EW, and deliver predictable, high-performance capability across the electromagnetic spectrum.

For more information about our RF solutions for wideband, high-power systems, visit our EW solutions page. Additionally, you can find more interesting collateral on this subject by visiting our Qorvo Design Hub for a rich assortment of videos, technical articles, white papers, tools and more. For technical support, please visit Qorvo.com or reach out to Technical Support.

From Laptops to the Cloud: Engineering a More Sustainable Digital World – Together

How Intel is advancing energy‑efficient computing across devices, systems and global data center infrastructure

As demand for AI and digital services accelerates, the responsibility to grow sustainably has never been greater. This Earth Day reminds us that in technology, efficiency matters as much as innovation—and sustainability must be built into every design choice we make.

Engineering Efficiency in Everyday Personal Computing

Pallavi_Pandit_Intel_1-1776891392296.png

When we talk about improving Personal Computer (PC) energy efficiency, Intel approaches it as a three-layer challenge—starting at the platform and silicon architecture, extending through system level tuning, and reinforced by software level insight and optimization. This matters because meaningful energy savings don’t come from a single feature or setting; they come from aligning how hardware is designed, how systems behave in real world use, and how software interacts with the platform over time. Intel’s focus is on reducing energy use during everyday operation—the phase of a PC’s lifecycle where users and IT teams have the greatest opportunity to lower power consumption while still getting the performance and AI enabled experiences they expect.

At the platform level, the latest Intel® Core™ Ultra Series 3 processors are designed with energy efficiency as a foundational architectural goal. These platforms improve performance per watt by tightly integrating compute, graphics, memory, and dedicated engines for specific workloads, allowing common tasks—and select AI workloads—to run in more energy‑efficient states rather than relying solely on high‑power CPU cores. This architectural approach helps scale energy use to actual demand, reducing wasted power during idle and light‑use scenarios while preserving responsive performance when workloads intensify.

That foundation is strengthened at the system and software layers, where intelligent tuning and clear visibility enable smarter, more efficient operations. At the system level, Intel® Dynamic Tuning Technology uses advanced AI‑ and machine‑learning–based algorithms, combined with real‑time telemetry, to dynamically adjust power and thermal behavior based on workload demand—helping balance performance, acoustics, and energy use without manual intervention. At the software level, the Intel® Battery Life Diagnostic Tool provides visibility into how applications, background processes, and system configurations affect a PC’s ability to reach low‑power states, including identifying software behaviors that limit efficiency. Together, Intel® Core™ Ultra architecture, Intel® Dynamic Tuning Technology, and the Intel® Battery Life Diagnostic Tool demonstrate an end‑to‑end approach to energy efficiency: design for efficient execution in silicon, optimize behavior intelligently at the system level, and continuously improve through software insight—ensuring efficiency gains show up in real‑world use.

Pallavi_Pandit_Intel_2-1776891392302.jpeg

Efficient Compute at Data Center Scale

When you send an email, stream a video, or use AI-powered apps, you’re connected to data centers. Intel’s commitment to sustainability means those experiences are powered by technology designed to be energy-efficient and environmentally responsible. Energy efficiency is the ultimate competitive advantage in the AI era, and Intel is committed to leading the way toward sustainable, high-performance data centers for a sustainable future.

Our approach to power more energy-efficient and cost-effective data centers is structured around four key layers, spanning the entire product lifecycle from design to data center operations:

  1. Design Layer: Energy Efficiency by Design
    Energy efficiency is integrated from the ground up during product design and development. Innovations include hardware optimizations, power benchmarks, regulatory compliance, and reducing embodied carbon. Intel® Xeon® 6 processors, for example, deliver up to 1.58x higher 1 performance per watt compared to prior generations, helping reduce energy consumption and carbon footprint.
  2. Monitoring Layer: Real-Time Power Telemetry
    Advanced CPU and platform telemetry systems monitor power usage in real-time. Tools like Intel® Application Energy Telemetry (Intel® AET) provide per-application, workload, and VM-level energy metrics, enabling data center operators to identify power consumption patterns and problem areas for better energy management.
  3. Measurement Layer: Precise Power Analytics
    Technologies such as Running Average Power Limit (RAPL) and residency counters measure power consumption accurately. The Power and Performance Excursion Monitor (PEM) alerts operators to thermal and power limit events to prevent hardware damage. Intel® Platform Monitoring Technology (Intel® PMT) and Topology-aware Power Management Interface (TPMI) provide unified monitoring across server topologies.
  4. Optimization Layer: Intelligent Power and Cooling Management
    Technologies like intelligent rack overprovisioning and Intel® Infrastructure Power Manager (Intel® IPM) optimize power usage dynamically. Power management features include Intel Optimized Power Mode (Intel OPM), Fast C1e states, Core C6 deep sleep states, and Enhanced Latency Control (ELC). Cooling innovations such as direct-to-chip cold plates and immersion liquid cooling capture up to 100% of heat for efficient thermal management. These solutions reduce operational costs, improve total cost of ownership (TCO), and support sustainability goals.

Our impact is reflected in how these solutions are being deployed around the world. Intel® Xeon® 6 processors can deliver up to an 80% reduction2 in power consumption for AI image classification workloads compared to older generations, helping data centers do more with less energy. Server consolidation further lowers carbon footprint while reducing physical data center space. Through collaborations with Shell and Submer, Intel has helped enable the industry’s first certified immersion cooling solution for AI infrastructure. At the University of Waterloo, the Nibi supercomputer—powered by Intel Xeon 6 processors and liquid cooling—has become Canada’s first large‑scale immersion‑cooled supercomputer, supporting more than 4,000 researchers in a more sustainable way. And in hyperscale environments, Microsoft Azure uses Intel® Enhanced Latency Control to deploy more servers within existing data center footprints, improving performance per watt while reducing overall power consumption..

Advancing Technology, Protecting What Matters Most

By designing energy‑efficient platforms that scale with the world’s needs, we’re helping ensure digital innovation advances responsibly. It reflects our commitment to progress with purpose: delivering the performance people rely on, while caring for the planet and the resources we all share.

Global Partnership to Power Next-Generation, High-Speed Connectivity for Future Kentucky Derby Experiences and Across CDI Properties

Louisville, KY., (April 15, 2026) – Cisco (Nasdaq: CSCO) and Churchill Downs Incorporated (“CDI” or “the Company”) (Nasdaq: CHDN) today announced a multi-year partnership to significantly enhance the networking capabilities at the historic Churchill Downs Racetrack (“Churchill Downs”). As the Official Enterprise Networking and Network Infrastructure Partner of the Kentucky Derby, Cisco’s industry-leading AI-ready secure networking platform and solutions will bring simplicity, visibility, reliability and protection across the organization’s expansive digital footprint.

This partnership represents a significant investment in the future of connectivity at Churchill Downs, designed to support next-generation fan experiences at future Kentucky Derby Weeks and other year-round events. The network refresh — spanning more than 7,000 switches and a modernized routing fabric — will deliver high-speed, high-capacity connectivity across all CDI properties built for performance at scale for one of the world’s largest sporting events.

With 12 regional casinos and 18 live and historical racing venues, CDI operates a large and complex network environment. By consolidating capabilities under Cisco Catalyst Center, the Company will enhance visibility, security and control while delivering faster, more reliable connectivity across all locations. Throughout the partnership, Cisco and CDI will continue to advance wireless and routing innovations to further strengthen speed, performance and digital resilience across the enterprise.

“This partnership with Cisco reflects our commitment to providing a world-class experience for our guests by modernizing and connecting our core technology platforms across networking, security, and observability,” said Nate Simon, Senior Vice President and Chief Technology Officer at CDI. “With Cisco’s technology, we will deliver faster, more connected experiences across our properties, while enhancing security and ensuring reliable operations — from everyday guest interactions to the scale of the Kentucky Derby.”

For the 350,000+ fans who attend the Kentucky Derby Week events each year, this network upgrade will ensure a seamless digital experience — from mobile ticketing and high-speed access to betting platforms like TwinSpires.com to the ability to share high-definition content in real-time. For Churchill Downs staff, the modernized infrastructure provides the reliable, high-speed connectivity required for point-of-sale systems to process food and beverage and wagering transactions without interruption, significantly reducing wait times and ensuring that operations run with the precision expected of the world’s most iconic horse race and cultural event.

“Racetracks like Churchill Downs don’t just require speed on the track — they demand it from their networks,” said Anurag Dhingra, SVP & GM, Enterprise Connectivity & Collaboration, Cisco. “Cisco’s networking technology delivers real-time, reliable connectivity that keeps every moment, from the grandstands to the winner’s circle, running flawlessly.”

CDI will leverage Cisco’s unified on-premises networking platform, powered by Catalyst Center, to centrally manage, secure and automate its enterprise network. With Catalyst Center, CDI can streamline operations through zero-touch provisioning, policy-based automation, and orchestrated rolling upgrades that help minimize disruption while maintaining reliable connectivity across its venues. Cisco Success Tracks will further support CDI with efficient asset tracking and proactive software management for secure, high-performing network operations. Use of Splunk Observability Cloud will ensure greater digital resiliency across the entire CDI digital environment, including the performance of TwinSpires and Churchill Downs application infrastructure throughout the year to deliver a seamless user experience, especially on peak days during Kentucky Derby Week.

For more than a decade, marquee sports teams, events, organizations and venues around the world have relied on Cisco technology and expertise, including McLaren Mastercard Formula 1 Team, Real Madrid F.C., United States Golf Association (USGA), Live Nation Entertainment, Madison Square Garden and many more.

About Churchill Downs Incorporated

Churchill Downs Incorporated (“CDI”) (Nasdaq: CHDN) has been creating extraordinary entertainment experiences for over 150 years, beginning with the company’s most iconic and enduring asset, the Kentucky Derby. Headquartered in Louisville, Kentucky, CDI has expanded through the acquisition, development, and operation of live and historical racing entertainment venues, the growth of online wagering businesses, and the acquisition, development, and operation of regional casino gaming properties. ChurchillDownsIncorporated.com

About Churchill Downs Racetrack

Churchill Downs Racetrack (“CDRT”), the world’s most legendary racetrack, has been the home of The Kentucky Derby, the longest continually held annual sporting event in the United States, since 1875. Located in Louisville, CDRT features a series of themed race days during Derby Week, including the Kentucky Oaks, and conducts Thoroughbred horse racing during three race meets in the Spring, September, and the Fall. CDRT is located on 175 acres and has a one-mile dirt track, a 7/8-mile turf track, a stabling area, and provides seating for approximately 60,000 guests. The stable area has barns sufficient to accommodate 1,400 horses and a 114-room dormitory for backstretch personnel. CDRT also has a year-round sports book and simulcast wagering facility. www.ChurchillDowns.com.

About the Kentucky Derby

The $5 million Kentucky Derby takes place on the first Saturday in May at historic Churchill Downs Racetrack in Louisville, Kentucky. Inaugurated in 1875, the legendary 1 1/4-mile race for 3-year-old Thoroughbreds is the longest continually held major sporting event in North America and the first leg of horse racing’s Triple Crown series. Also known as The Run for the Roses® and The Most Exciting Two Minutes in Sports®, the Kentucky Derby is the most attended horse race in the nation. The 152nd Kentucky Derby will take place on Saturday, May 2, 2026. KentuckyDerby.com

About Cisco Cisco (NASDAQ: CSCO) is the worldwide technology leader that is revolutionizing the way organizations connect and protect in the AI era. For more than 40 years, Cisco has securely connected the world. With its industry leading AI-powered solutions and services, Cisco enables its customers, partners and communities to unlock innovation, enhance productivity and strengthen digital resilience. With purpose at its core, Cisco remains committed to creating a more connected and inclusive future for all. Discover more on The Newsroom and follow us on X at @Cisco.

Cisco and the Cisco logo are trademarks or registered trademarks of Cisco and/or its affiliates in the U.S. and other countries. A listing of Cisco’s trademarks can be found at http://www.cisco.com/go/trademarks. Third-party trademarks mentioned are the property of their respective owners. The use of the word ‘partner’ does not imply a partnership relationship between Cisco and any other company.

Growth should feel like progress.

But for a lot of MSPs, there comes a point where growth starts to feel heavier instead. New clients are coming in, and revenue is rising, yet the day-to-day operation feels more stretched, not more efficient. The service desk is constantly busy. Senior techs keep getting pulled into escalations. The team is working harder just to maintain the same standard of delivery.

The usual response is to hire more people. On paper, it makes sense. More demand requires more capacity. In practice, it’s where margins start to plateau because hiring doesn’t fix the underlying problem, it just helps you keep up.

The linear model that breaks margins

Most MSPs experience demand in a simple, linear way: More clients mean more tickets, and more tickets require more staff. It feels logical because it reflects what the team sees every day: More endpoints, user issues, performance complaints, and security-related noise.

But the model only works for so long, and isn’t scalable.

Headcount is one of the most expensive and least flexible ways to increase capacity. It comes with recruiting pressure, onboarding time, management overhead, and ongoing labor costs. It also increases dependency on specific individuals, which creates real risk when key technicians leave, burn out, or simply become the bottleneck.

It’s the daily MSP leader balancing act: Protect service quality and keep clients happy, without letting labor costs eat margins.

The real constraint isn’t demand

The hard truth is that most service desks aren’t under pressure because of major incidents every day. They are under pressure because of volume. Small, repetitive (and often preventable) issues that fill the day and steadily drain capacity like:

  • Alerts that need validation
  • Tickets that shouldn’t exist in the first place
  • Investigations that go nowhere
  • Routine tasks that feel unavoidable, but don’t move the business forward

This is operational noise, and it exists regardless of how many techs you hire.

When you hire more people, you increase your ability to process that noise, but you don’t reduce the amount of it. The same patterns keep creating the same work, and over time, you end up with a larger team handling the same problems at a higher cost.

Growth becomes less profitable because revenue rises, but the cost of delivering it rises right alongside it. Your margins don’t improve because the system underneath the business hasn’t changed.

The hidden cost is where your best people spend their time

As the linear model scales, your most capable people stop doing your most valuable work.

When senior staff are tied up in low-value investigations, constant escalation, and reactive firefighting, they are not improving the business. They’re being pulled away from the work they should be focused on, like standardizing service delivery, building repeatable processes, rolling out new security offerings, or creating operational improvements that increase margins over time.

The business keeps moving but it doesn’t move forward as it should, and it’s one of the clearest signs that the system is under strain. Your most experienced people are spending too much of their time protecting the present and not enough improving the future.

Reduce the work, scale well

The MSPs that scale most effectively don’t focus solely on adding capacity. Instead, they focus on reducing the effort required to deliver their services. That starts with prevention.

Every security event that reaches the helpdesk has already created work for the team. There is detection, alerting, triage, investigation, remediation, client communication, and the usual context switching that breaks a technician’s flow. Even if the event turns out to be harmless, the time has already been spent.

Across dozens or hundreds of clients, that creates a significant operational load. The earlier you stop the problem, you stop a significant amount of “noisy” work from ever appearing.

Prevention creates a quieter operation

If you can stop threats before a connection is made, a payload is downloaded, or an alert is generated, you remove the whole chain of downstream effort.

Fewer threats getting through means fewer alerts, fewer tickets, fewer investigations, and less need for senior escalation on routine security issues.

The impact is a quieter system that allows each technician to support more users and endpoints without constantly feeling stretched. It makes onboarding smoother because new clients don’t immediately feed unnecessary noise into the service desk. It gives the business a more predictable cost base and reduces the need to keep solving the same operational problems with more people.

Over time, it stabilizes your cost base. Instead of revenue and headcount rising together, you increase the number of clients each technician can support. Margin improves not because you charge more, but because it costs less to deliver the same service at the same (or higher) standard.

The advantage of provable value

When your security approach is preventative rather than reactive, the conversation with clients changes. You are no longer limited to showing how many tickets were closed or how quickly incidents were handled. You can show how much disruption and risk was avoided in the first place.

Value is easier to demonstrate because the outcome isn’t activity; it’s stability.

That creates a stronger foundation for pricing, packaging, and expanding security services.

Growth isn’t a bigger team, it’s a better system

Hiring more techs will always increase capacity in the short term.

But it will not, on its own, make your MSP more scalable. It will not reduce operational noise, simplify delivery, or lower the cost to support each client.

Only removing unnecessary work from the system does that. That is what separates growth from profitable growth. Not a bigger team, but a better operating model.

Learn how DNSFilter helps MSPs cut ticket volume, reduce technician workload, and improve margins at the DNS layer; start your free trial today.

In the embedded systems world, embedUR has spent the last twenty years in the trenches. We’ve built the wireless infrastructure that runs enterprise access points and the residential gateways sitting in millions of homes. In that time, we’ve learned one thing: regulatory shifts aren’t just legal problems. They are engineering problems.

The EU Cyber Resilience Act (CRA) is one of the biggest shifts we’ve seen in a decade. It isn’t just a footnote in a policy briefing; it’s a fundamental change in how we need to or should design, build, and most importantly, sustain products. At embedUR, we’ve guided teams through every Wi-Fi evolution from the early days of 802.11n to the complexities of Wi-Fi 6E and the new world of tinyML at the edge.

From where we stand, the CRA shouldn’t be a headache. It should be the catalyst that finally forces the industry to build smarter, more resilient systems.

But let’s be honest: for an engineering lead trying to hit a product launch date while staring down resource gaps, the CRA looks like a mountain of paperwork. To climb it, you have to bridge the gap between using an open-source RTOS like Zephyr and meeting the rigorous demands of European law.

The Clock is Ticking: Understanding the CRA Milestones

We are currently in early 2026. The grace period is evaporating. The CRA was formally adopted back in late 2024, and the first major hammer will drop on September 11, 2026. That is the date when mandatory vulnerability reporting goes live.

If your device has a digital element and you sell it in the EU, you have 24 hours to report an exploited vulnerability. Not 24 hours after you fix it—24 hours after you find it.

By December 2027, the remaining requirements kick in: security-by-design as a legal mandate, machine-readable Software Bills of Materials (SBOMs), and a 5-year support window. If you miss these marks, the fines are eye-watering: up to €15 million or 2.5% of your global turnover. For any U.S. company exporting to Europe, which is a massive chunk of the global market, this is now the cost of doing business.

Why Zephyr is our Go-To (And Why It’s Not a Silver Bullet)

We’ve been working with Zephyr RTOS since its early releases in 2016. It’s under the Linux Foundation, it’s transparent, and it’s modular. On paper, it’s the perfect answer to the CRA.

Zephyr’s PSIRT (Product Security Incident Response Team) is excellent. They handle CVEs (Common Vulnerabilities and Exposures) with a level of transparency that mirrors the Linux kernel. When a bug is found in the networking stack, the fix is public and documented.

Furthermore, the Long-Term Support (LTS) releases, like the 3.7 LTS, offer five years of security maintenance. That perfectly maps to the CRA’s support requirements.

Zephyr also gives us the “West” tool. Using west spdx, we can generate an SBOM automatically during the build process. If you’ve ever tried to manually track every library and sub-component in a proprietary RTOS, you know that automated SBOM generation is a godsend. It takes the drudgery out of compliance.

However, this is the local engineer’s truth: upstream Zephyr is not the same thing as a shipping product.

The Reality of “The Fork” and Maintenance Debt

Here is where the theory hits the floor. In our work sustaining Wi-Fi products for major global brands, where we manage fleets of over 10 million units, we’ve seen divergence as a major problem.

An engineer starts with a clean Zephyr LTS branch. Then, the silicon vendor provides a HAL (Hardware Abstraction Layer) that isn’t quite right for the specific power constraints of a Cortex-M4 gateway. So, the engineer tweaks the kernel. Then the marketing team requests a specific feature that requires a custom driver. Before you know it, you’ve forked the repo.

When a security patch comes down from the Zephyr upstream six months later, it doesn’t fit. It breaks your custom power management. It conflicts with your Wi-Fi driver. Now, compliance means a three-week rebase and a full regression test.

If you have a multi-SKU product line, maybe some devices use ARM and others use RISC-V, your vulnerability tracking turns into a nightmare. There are cases where a field-reported bug traced back to an unpatched erratum in a silicon vendor’s HAL. Because the team had drifted too far from the clean upstream code, they couldn’t pull the fix. 

This kind of delay is exactly what the CRA will penalize.

The tinyML Constraint

The complexity doubles when you add tinyML. We’re seeing more industrial gear using TensorFlow Lite Micro on Zephyr to do predictive maintenance at the edge. These models are ultra-constrained. Every byte of RAM matters.

When you’re fighting for every kilobyte to make an AI model work on an IoT sensor, security overhead feels like an enemy. But under the CRA, that edge intelligence is part of the product’s digital footprint.

If your ML inference engine has a buffer overflow vulnerability, you are liable. Shoehorning these models into Zephyr while maintaining a secure, updatable bootloader (like MCUboot) requires a level of memory management that most teams aren’t prepared for.

Making Compliance a Competitive Edge

So, how do we stop compliance from being a burden and turn it into a reason why customers choose you over a competitor? You have to treat security as a feature, not a chore.

1. Stop Wild Forking

The biggest mistake we see is that engineers treat Zephyr like a one-off download. You have to stay aligned with the LTS branches. We recommend a “cherry-pick” strategy. You pin your project to a stable LTS version and build a rigorous process for pulling in only the security patches you need. This keeps your custom “secret sauce” separate from the core RTOS plumbing.

2. Automate the Paperwork

If an auditor asks for your SBOM, you shouldn’t have to spend a week in Excel. We help our clients integrate SBOM tools directly into their CI/CD pipelines (like GitLab or GitHub Actions). 

Every time a developer pushes code, the system should automatically run a vulnerability scan (using tools like grype or trivy) and generate a new SPDX file. If a vulnerability is found, the build should fail before the code ever reaches a device.

3. Standardize via Device Tree Overlays

To handle the multi-SKU headache, we use Zephyr Device Tree overlays. Instead of having different codebases for different hardware, you keep one core application and use overlays to describe the hardware differences. This minimizes code drift and ensures that a security patch for your BLE stack works across every device in your catalog.

4. Hardware-in-the-Loop (HiL) Testing

You can’t trust a simulation for CRA compliance. You need automated test rigs where real hardware is subjected to simulated exploits. At embedUR, we’ve built environments where we test everything from LTE stack vulnerabilities to timing glitches in crypto libraries. 

This is how you catch a DoS (Denial of Service) bug before it gets found in the field and  becomes a mandatory 24-hour report to the EU.

The embedUR Difference: Real Engineers, Real Solutions

This is what we do. We aren’t a compliance consultancy that just hands you a PowerPoint. We are an engineering firm with over 400 expert embedded systems engineers who live in the kernel. Our architects have upstreamed code to Zephyr’s networking modules. We also know the silicon vendors—NXP, Infineon, Nordic, and Silicon Labs—and where their HALs usually break.

We have the sustainment framework ready to go. We handle the kernel upgrades, the CVE monitoring, and the SBOM maintenance so that your senior engineers can focus on the stuff that actually makes you money, like your next-gen predictive maintenance algorithms or your cloud-to-edge analytics.

The Bottom Line

The September 2026 deadline is closer than it looks on the calendar. In the world of embedded systems, eighteen months is one design cycle. If you start thinking about the CRA during the testing phase, you’ve already lost.

Is your Zephyr setup a solid foundation, or is it a house of cards? If you’re building for the EU market and worried about staying compliant without killing your product roadmap, let’s talk.

We can do a technical review of your current stack and show you exactly where the gaps are. We’ve been through the Wi-Fi wars and the IoT explosion; we can get you through this, too.

Let’s get your engineering team back to innovating. Schedule a Technical Review: Talk directly with our lead architects about your current Zephyr stack and CRA gaps.

For more than a decade, wireless microcontrollers (MCUs) have been evaluated primarily on radio performance. Range, sensitivity, protocol support, and transmit power defined leadership. These metrics still matter, but in modern IoT systems, connectivity is no longer the primary constraint. System complexity is.

Rethinking the Role of the IoT MCU

Today’s IoT products are expected to deliver more intelligence, tighter power efficiency, and faster time to market, all while reducing cost. Yet many designs still rely on multiple MCUs operating on the same board. A single device might have one MCU for connectivity, another for application control, and a third for real-time processing. And sometimes a fourth is required for sensing or device management.

This architecture persists because it’s familiar. But it’s far from optimal.

As IoT systems evolve, RF performance alone is no longer the defining metric. What matters today is how efficiently the entire system is architected.

Silicon Labs Series 2 was designed around the premise that wireless MCUs should not just connect devices, but consolidate them.

The Hidden Inefficiency in Today’s IoT Designs

A typical connected device often includes:

  • A wireless SoC for Bluetooth Low Energy (LE), Zigbee, Thread, or proprietary connectivity
  • An application MCU for control logic
  • A motor-control MCU for deterministic actuation
  • A low-power controller for sensing or housekeeping

Each additional device increases:

  • Bill-of-material cost (BOM)
  • PCB area
  • Firmware complexity
  • Validation effort
  • Inter-processor latency
  • Idle and leakage power

Ironically, much of this duplication is unnecessary. Wireless workloads are event-driven and burst-based. In many systems, the connectivity stack consumes a fraction of available CPU cycles. The processor becomes active during packet handling, then remains idle for extended intervals.

This creates a structural inefficiency. Significant compute headroom remains unused while additional MCUs are added elsewhere on the board. This presents an opportunity to reclaim that headroom and consolidate system functionality without compromising wireless performance.

Consolidation Only Works if Isolation is Guaranteed

The primary reason many systems remain partitioned is concern. Engineers hesitate to combine workloads for fear of degrading wireless determinism or introducing timing jitter into real-time tasks.

Silicon Labs Series 2 addresses this directly. It employs a multicore, event-driven architecture with functional separation:

  • Dedicated cores manage radio and security operations
  • Latency-critical wireless tasks execute independently
  • The application core remains available for control, sensing, and AI workloads

This separation ensures that adding application functionality does not degrade wireless performance or real-time behavior. Instead of protecting RF integrity through partitioning, designers can now protect it through architecture.

Event-Driven Compute: Doing More with Less Power

Reducing component count is only part of the system equation. Power efficiency is equally critical. Traditional MCU-based systems rely heavily on CPU intervention. Interrupt-driven designs wake the processor frequently, increasing dynamic power consumption and adding software overhead.

Series 2 takes a fundamentally different approach.

Its Peripheral Reflex System enables peripherals to communicate directly with one another. Hardware events trigger hardware responses. Data can move through DMA pathways without waking the CPU.

For example:

  • An ADC conversion can automatically initiate a memory transfer
  • A comparator event can directly adjust a PWM output
  • Timers can coordinate control loops autonomously

The processor wakes only when meaningful computation is required. This architecture delivers:

  • Lower dynamic power consumption
  • Deterministic real-time behavior
  • Higher effective compute utilization

More work is done in hardware, so less energy is spent orchestrating it in software. In battery-powered and energy-sensitive systems, this is a structural advantage.

Real-Time Control and Connectivity on One Chip

Motor control illustrates the consolidation challenge clearly.

Closed-loop Field-Oriented Control (FoC) demands precise timing, high-speed ADC sampling, and coordinated PWM updates. Historically, this required a dedicated MCU to guarantee deterministic performance.

Series 2 challenges that assumption.

By combining advanced PWM peripherals, high-performance ADCs, hardware-based event routing, and efficient Arm Cortex-M33 processing, Series 2 can execute closed-loop FoC while simultaneously maintaining a Bluetooth LE stack on the same device.

This enables:

  • Single-chip motor and wireless designs
  • Reduced system latency
  • Simplified firmware architecture
  • Lower PCB complexity

For customers, the impact is direct:

  • BOM reduction
  • Lower power consumption
  • Shorter validation cycles
  • Faster time to market

The economics of intelligent devices shift when real-time control and connectivity coexist on one platform.

Embedded AI Without Additional Silicon

The next generation of IoT systems requires local intelligence. Sensor fusion, anomaly detection, predictive maintenance, and signal classification are increasingly moving from cloud to edge.

Traditional approaches add hardware. External NPUs or larger application processors increase cost, board space, and power complexity.

Series 2 integrates a Matrix Vector Processor (MVP) optimized for linear algebra, DSP workloads, and neural network inference.

By offloading math-intensive operations:

  • CPU cycles remain available for control and connectivity
  • Inference latency becomes predictable
  • Energy per inference is significantly reduced

AI becomes a native system capability rather than an architectural add-on. Intelligence is integrated, not appended.

Platform Consistency That Scales

Architectural consistency is as important as performance.

Series 2 capabilities extend across Bluetooth, multiprotocol, sub-GHz, and proprietary families. Motor-control peripherals, AI acceleration, event routing, and security architecture are shared across the portfolio.

This enables:

  • Software reuse across product variants
  • Reduced SKU proliferation
  • Simplified qualification processes
  • Faster feature scaling

As organizations expand product lines or enter adjacent markets, a consistent platform reduces both technical and operational friction. Platform continuity becomes a multiplier for engineering productivity.

Connectivity is No Longer the Edge of the System, It’s at The Center

Many vendors approach connectivity by adding radios to traditional MCU architectures.

Series 2 takes the opposite path by absorbing application compute, control logic, and AI into the wireless platform itself. Instead of adding features through more silicon, the objective becomes removing silicon entirely.

In modern IoT systems, leadership will be measured by:

  • How many components can be eliminated
  • How efficiently compute headroom is utilized
  • How intelligently power is managed
  • How seamlessly functionality scales

A New Definition of the Wireless MCU

Series 2 redefines what a wireless MCU can be. A connectivity platform, an application processor, a real-time control engine, and an embedded AI accelerator. All within a single, power-efficient architecture optimized for real-world IoT systems.

As IoT architectures continue to consolidate, the question is no longer whether wireless MCUs should do more.

The real question becomes, how efficiently can they replace the rest of the system?

Series 2 was designed for this future from day one.

In modern IoT design, the most valuable innovation may not be what is added to the board, but what can finally be removed.

Change is coming to NETGEAR® Insight™, and it’s designed entirely around you.

In the coming weeks, all Insight customers will automatically receive a significant platform update. This evolution enhances the user experience, simplifies workflows, and provides a strong foundation for long-term scalability—while preserving the secure, cloud-based management you rely on every day.

More than a visual refresh, this thoughtful redesign is the direct result of your feedback and is built to support the way SMEs and MSPs manage networks today.

A Modern Interface Built for Clarity

The first thing you’ll notice is a refreshed, contemporary interface. Built on a Material UI (MUI) foundation—an industry-standard design system— the new experience is cleaner, more consistent, and easier to navigate.

From typography to layout structure, every element has been refined to reduce friction and improve usability. Whether you’re managing a single site or a multi-organization deployment, the interface is designed to help you move faster and work smarter.

Simplified Navigation and Hierarchy

Managing multiple locations and customers requires speed and precision. The updated Insight experience introduces a more intuitive menu system and an improved hierarchy tree that makes navigating organizations, locations, and devices significantly more efficient.

Instead of clicking through layered menus, you can now access what you need with fewer steps. The result is less time spent searching and more time spent managing.

For MSPs and IT administrators managing complex environments, this means faster navigation, fewer clicks, and more time focused on delivering results for customers.

Faster Onboarding, Faster Deployment

Time matters – especially during deployment.

The updated Insight platform introduces a simplified two-step customer sign-up process and an accelerated device onboarding workflow. These enhancements remove unnecessary steps and reduce setup friction, allowing teams to bring networks online more quickly.

Whether you’re deploying a new location or expanding an existing network, the improved onboarding flow helps ensure faster time to value.

A Streamlined Subscription Model

We’ve also simplified the commercial side of Insight.

The new single-tier subscription model replaces multiple tiers with one streamlined option. This change reduces confusion, simplifies purchasing decisions, and makes subscription management easier for both partners and end customers.

For MSPs, this means more straightforward conversations and fewer administrative complexities. For IT managers, it means clarity and predictability.

Built for Scale

Insight continues to deliver secure, cloud-based control of routers, switches, access points, and mobile hotspots—all through a single pane of glass.

The updated architecture and navigation improvements make the platform even more scalable. Whether you manage one business with several locations or a portfolio of clients across industries, Insight is engineered to grow with you.

The improved structure supports expanding device counts, additional sites, and evolving organizational needs without increasing management complexity.

Reliable, Secure Cloud Foundation

While the interface evolves, the foundation remains the same: secure, resilient cloud infrastructure designed to protect your data and ensure continuity.

Insight continues to operate on NETGEAR’s trusted cloud-native platform, allowing devices to function even if cloud connectivity is temporarily interrupted. Security remains a priority, with enterprise-grade protections and robust access controls built into the system.

This update enhances the experience—but it does not compromise the reliability you depend on.

What You Need to Do

Nothing.

The update will automatically apply to your existing Insight environment. Your configurations, data, organizations, and devices will remain intact.

We will share updated documentation and resources to help you quickly familiarize yourself with the new interface, but no reinstallation or migration steps are required.

Designed for the Way You Work

This next evolution of Insight reflects a simple principle: powerful technology should feel effortless.

By modernizing the interface, streamlining navigation, accelerating onboarding, and simplifying subscriptions, we’re making it easier for IT teams and MSPs to manage networks with confidence and clarity.

We’re excited for you to experience what’s next.

Stay tuned for additional updates as we approach launch.
Genio Pro 5100: Extreme Compute & Multimedia Platform Unleashes the Full Potential of IoT AI

IoT is now powering intelligent, autonomous systems, so developers need platforms that can handle real-time AI at the edge without sacrificing efficiency or scalability. That is exactly where the MediaTek Genio Pro comes in.

The MediaTek Genio Pro is a flagship platform designed for extremely high-performance, AI-driven embedded systems. Built on a cutting-edge 3nm process and equipped with an advanced AI processing unit capable of delivering over 50 TOPS of compute, it enables everything from real-time vision systems to on-device generative AI. With support for large language models, multi-camera inputs of up to 16, and rich multimedia capabilities such as 8K video, it is ready to support even the most demanding and varied applications.

MediaTek Genio Pro_Bento Infographic 032611 conv 1

Different industries will find unique value propositions in the MediaTek Genio Pro:

Robotics and Autonomous Systems Developers
Autonomous mobile robots or drones will benefit from Genio Pro’s sensor fusion, ROS2 support, and real-time AI inference, which allow them to sense, see, and make decisions instantly. It can process data from multiple cameras while running AI models locally, which is critical for navigation and decision making without cloud latency.

Industrial IoT Engineers
For factory automation, predictive maintenance, or machine vision, the platform’s certification for industrial temperatures ensures it fits demanding environments. High compute density combined with exceptional power efficiency lowers total cost of ownership by reducing lifetime power consumption, minimizing reliance on communication infrastructure, and lowering cloud server costs. Combined with Linux support including Yocto, Ubuntu, and Debian, it integrates smoothly into existing industrial stacks.

Smart Retail and Commercial IoT Builders
Developers working on smart kiosks, digital signage, or customer analytics systems can leverage multi-display support and edge AI to deliver personalized, real-time experiences throughout the store, all from a single device.

Edge AI and Generative AI Innovators
With on-device LLM capabilities that handle models up to 7B parameters, Genio Pro opens the door to private, low-latency generative AI applications, from intelligent or agentic assistants to advanced analytics at the edge.