Think of the connected home network as a brain. For years, every device, a smartphone, a laptop, a smart TV all connected to a single access point and relied on that one pathway. Each Wi-Fi generation improved that single wire: higher modulation, higher bandwidth, more channels yielding more throughput. But the fundamental architecture remained unchanged.
Wi-Fi 8 changes the anatomy fundamentally. It creates new additional neural pathways, enabling devices to connect to multiple APs simultaneously and allowing those APs to coordinate like interconnected clusters of neurons. For operators, this isn’t just a PHY upgrade, it’s the foundation for a genuinely intelligent home network. And that’s precisely where the opportunity lies.
Wi-Fi 8 (IEEE 802.11bn) introduces several capabilities that promise significant improvements in the end-user experience in terms of reliability and low latency:
Wi-Fi 8’s value is not automatic. The standard builds the neural pathways and establishes a shared language between APs. But pathways alone don’t produce intelligent behaviour.
Without a coordinating layer, a cortex if you like, APs can exchange information without making better decisions. Operators who deploy Wi-Fi 8 hardware without investing in the orchestration layer will see incremental gains. Those who pair the standard with intelligent coordination will see transformational ones that will bring them to the number one broadband provider in their market.
Airties provides the orchestration layer that closes the gap as our AI platform turns raw Wi-Fi 8 signals into smart, measurable network actions. There are four capabilities define the value:
Seamless mobility: Video calls and AR/VR sessions remain stable as subscribers move through the home. Multi-AP session continuity eliminates mid-call drops and re-buffering — and the support tickets that follow.
Low-latency gaming: Edge orchestration minimizes jitter and latency for especially latency intolerant applications where every millisecond matters. Airties detects and prioritizes gaming traffic per-household and per-session without manual configuration by the subscriber or the operator.
Tailored household profiles: The network optimizes per-home behaviour automatically. A household with a home office receives different QoS treatment than one with three gaming teenagers. Profiles are automatically learnt, dynamically applied, and continuously refined per home.
Reduced OPEX and support costs: Smarter orchestration eliminates the most common subscriber complaints like slow zones, sudden drops, congested channels. The result is measurable improvement in NPS and lower cost-per-resolution.
In summary, Wi-Fi 8 builds the neural pathways. The standard creates a shared language between APs. But pathways alone don’t produce intelligent behaviour, you do need a connected home ‘cortex’ to interpret, evaluate, optimize and apply.
Airties is that cortex. We have decades of orchestration expertise, hundreds of patents, proven automated proactive remote network management, mesh and client-steering experience, and a hybrid edge/cloud AI architecture that turns Wi-Fi 8’s potential into real, measurable subscriber value, and most importantly measurable operator ROI.
Under new leadership, global connectivity provider recognized for culture transformation, employee-first approach and deep emotional connection across a worldwide team
PALO ALTO, CA — April 15, 2026 — Plume Design, Inc. (“Plume”), the global technology leader trusted by more than 450 Internet Service Providers (ISPs) across 58 countries, today announced it has earned Most Loved Workplace® Certification from Most Loved Workplace® and the Best Practice Institute less than one year after launching a company-wide culture transformation initiative under new leadership. This certification, based on the proprietary Love of Workplace Index® (LOWI) framework, is awarded to organizations where employees demonstrate the deepest levels of positive sentiment, shared values and emotional connection to their work. Plume will be featured among certified Most Loved Workplaces® in upcoming editions in The Economist (May 2026) and The Wall Street Journal (October 2026).
The recognition marks a significant milestone in a deliberate transformation. When Dan Herscovici assumed the role of President and CEO in April 2025, he made culture one of the company’s first strategic priorities. Over the past year, the company has undertaken a company-wide culture initiative anchored in rebuilding trust, strengthening accountability and ensuring every Plume team member feels they belong and can do their best work. The results can be measured through the LOWI framework and are reflected in employees’ own words, describing their experiences.
“There is a beautiful collaborative spirit that runs through Plume. We problem solve as a team, challenging each other in a psychologically safe manner, to come up with the best solutions. We have a shared desire to deliver excellent service to our customers.”
“The company’s focus on improving culture has helped me grow personally and professionally. There is a new direction that was missing previously and now there is always something new to learn.”
“The new tone that is being set at the top of the company is refreshing and reaffirming. Plume has clear goals, and what we are working towards is exciting. My colleagues, including supervisors and team members, are all great to work with.”
“We have an incredible culture of transparency, empowerment and accountability. Every day we have interesting, technical challenges to solve, which is rewarding. Our leaders give us the right balance of support and autonomy.”
“When I joined Plume, I came to a company with extraordinary technology and an outstanding team of professionals that wanted to believe in where they worked, so we made creating a great culture and rewarding work environment one of our top objectives,” said Mr. Herscovici. “We treated it as a business imperative, because you cannot deliver world-class experiences for 450 ISP customers if the people building the products and solutions don’t feel respected and heard. Building better connections is not just a tagline, it is a commitment that we strive for every day, not only with our customers, but equally with our team members. This recognition reflects the genuine commitment we have made to implementing changes that employees can see and feel. We are proud of being recognized for our efforts, and we intend to keep earning our team members’ trust and respect.”
“Culture transformation at a company with offices around the world doesn’t happen by sending an email,” said Lorie Boyd, Chief People Officer at Plume. “We set out to rebuild trust, to create real accountability and to make sure every team member, in every country we operate, felt seen and supported. What made this real was that we didn’t treat it as an HR initiative. It was a complete commitment from the CEO down through the entire organization. The words our employees used to describe their experiences here tell us the work is landing. That is what matters most.”
Most Loved Workplace® certification is earned following LOWI assessment across the five SPARK dimensions: Systemic Collaboration, Positive Future, Alignment of Values, Respect and Killer Outcomes.
“What sets Most Loved Workplaces apart is not a score on a survey — it is the depth of emotional connection employees feel to their work, their colleagues and the future they are building together,” said Louis Carter, CEO and Founder of Best Practice Institute and Most Loved Workplace®. “Plume demonstrates exactly what the SPARK model reveals in the highest-performing organizations: a positive vision of the future that people believe in, values that are lived not posted and leaders who create the conditions for people to love where they work. That is not soft. That is a competitive advantage.”
Plume powers intelligent, cloud-managed Wi-Fi, security, and subscriber experience services for more than 450 ISPs globally — including Bell, Charter, Jio, J:COM, Liberty Global and FPT Telecom — delivering reliable, secure and personalized experiences across nearly half a billion connected devices worldwide.
The culture initiative coincides with a period of accelerating business momentum. Over the past 12 months, Plume has:
Plume joins a global community of certified companies recognized by Most Loved Workplace® for placing the emotional wellbeing and connection of their people at the center of how they operate. For more on why Plume was certified as a Most Loved Workplace®, visit https://mostlovedworkplace.com/companies/plume/.
Ms. Boyd will participate in a Most Loved Workplace hosted webinar, Rebuilding Belief in Employee Voice, on Wednesday, April 15 at 3 pm Eastern. Click here to register for the free webinar.
About Plume
Plume created the first managed Wi-Fi platform for Internet Service Providers (ISPs) in 2016 and continues to lead today with a best-in-class solution for cloud-managed Wi-Fi, security, and workflow orchestration – all powered by an unmatched dataset and AI. With almost half a billion devices connected to its platform, Plume is a trusted technology partner for more than 400 ISPs around the world, helping them deliver subscriber confidence through better Wi-Fi experiences, new services, and proactive customer care. Plume leverages OpenSync®, an open-source framework that comes pre-integrated and supported on the leading silicon, CPE, and platform SDKs, and supports leading industry standards like RDK-B and prplWave. Combined with powerful AI orchestration tools with its acquisition of Sweepr, Plume now offers ISPs a true end-to-end solution to power their most important workflows and customer experiences, while making deployment simpler and faster. Plume is leading the way in providing ISPs an intelligence and innovation edge to stay competitive, build subscriber confidence, and adapt to the changing needs of the market. Discover more about how Plume is empowering ISPs by visiting https://www.plume.com.
About Most Loved Workplace®
Most Loved Workplace® is a certification and research organization that identifies companies where employees demonstrate the deepest levels of positive sentiment and emotional connection, measured across the five SPARK dimensions: Systemic Collaboration, Positive Future, Alignment of Values, Respect, and Killer Outcomes. Certified Most Loved Workplaces® are eligible for inclusion on annual Top 100 lists featured in leading publications such as The Economist (Top 100 Global Most Loved Workplaces) and The Wall Street Journal (America’s Top 100 Most Loved Workplaces), and on broadcast features on CNBC, Fox Business, Bloomberg and others. Learn more at mostlovedworkplace.com.
Experiencing high ping or lag in Counter Strike 2 (CS2) can seriously ruin your performance—especially in a fast-paced, competitive game where milliseconds matter. Ping spikes, packet loss, or server lag can make aiming feel sluggish and completely throw off your reaction times.
In this guide, we’ll cover the top causes of lag in CS2 and show you how to fix them with proven network optimizations—whether the issue is server-side, on your Wi-Fi, or caused by congestion in your home network.
Before tweaking your settings or blaming your router, it’s smart to check if CS2 servers are down or under strain. With millions of players, server issues often pop up—especially after major updates or during peak times.
You can check live server status using:
Counter Strike 2 Server Status
If you can see other players are also experiencing CS2 lag, it’s likely a server-side problem—not your connection. While you can’t fix this directly, at least you’ll know the issue isn’t on your end.
One of the most common causes of lag and packet loss in CS2 is using Wi-Fi instead of a wired connection. Wireless signals are prone to interference, especially through walls or long distances. This often leads to packet burst, jitter, and unstable ping during matches.
The solution to this is to use a wired Ethernet cable to connect your PC directly to your router. This provides the most stable and reliable connection for online gaming. If you can’t run a cable to your router, consider using Powerline Adapters. These devices let you run an Ethernet connection through your home’s electrical wiring—perfect for multi-floor setups.
If your internet seems stable but you’re still experiencing high ping in Counter Strike 2, the problem might be hidden: connecting to distant servers or network congestion at home. That’s where the Netduma R3 gaming router and its powerful features comes in.
Powered by DumaOS 4, the R3 has three powerful gaming features that fix CS2 lag, ping spikes, and packet loss completely. If you want to see these features in action, check out our full Netduma R3 CS2 video below:
One major cause of CS2 high ping is being connected to a server that’s far away. Your data has to physically travel further, which naturally increases delay.
The Geo-Filter solves this issue by giving you the control of what servers you play on. Once setup, the Geo-Filter creates a customisable filter radius around your location. This filter blocks connection to far away, high ping servers and instead forces connection to nearby, low ping servers within your filter.
Pair this with Ping Heatmap, which shows the actual location and ping of CS2 servers globally. You’ll know exactly which servers give you the lowest ping—and can adjust your Geo-Filter settings accordingly.
Even with low ping, you might notice your gameplay feels inconsistent. That’s usually due to jitter—the constant fluctuation of your ping.
Steady Ping eliminates jitter by applying a small buffer that smooths out your ping. This results in almost perfectly stable response times and no micro-stutters in your connection. This makes your gameplay incredibly responsive, letting you hit more shots.
Even a few milliseconds of jitter can ruin your precision in CS2—especially in clutch moments. Steady Ping keeps your connection rock-solid.
If others in your home are streaming, downloading, or video calling, they could be eating up your bandwidth—causing lag in CS2, even on a good connection.
SmartBOOST fixes this by automatically detecting your CS2 traffic and prioritising it above other applications on your network. As gaming doesn’t amount of bandwidth, larger applications like streaming often take bandwidth away from gaming. SmartBOOST ensures gaming always receives the optimal amount of bandwidth, no matter how busy your network is.
By SmartBOOST ensuring each application on your network, it also eliminates bufferbloat on your network which will increase the responsiveness and stability of your gameplay even more
If you want to see SmartBOOST in action, watch our live demo showing how it eliminates lag on a congested network:
We aren’t just building faster connections; we’re building smarter privacy.
As Generative AI makes its way into the industrial sector, we have observed an increasing urgency among enterprises for data sovereignty. The challenge is no longer just about ‘how’ to implement AI, but ‘where’ and ‘how safely’ that intelligence operates.
At AsiaRF, we recognize that the cloud isn’t always the answer—especially when privacy, latency, and range are non-negotiable. This is precisely why the synergy between OpenClaw.ai and HaLowFly is so transformative. By bringing localized intelligence to the long-range capabilities of Wi-Fi HaLow, we are empowering businesses to reclaim their data autonomy while scaling their AIoT infrastructure like never before.”
Giving the Edge a Brain: Why the Convergence of OpenClaw.ai and HaLowFly Defines the New Private AIoT
As Generative AI moves into the industrial sector, we have observed an increasing urgency among enterprises for data sovereignty. In the next era of Industrial IoT, connectivity alone is no longer the finish line—it is the baseline. The real breakthrough occurs when edge devices can think, act, and communicate without ever touching the cloud.
At AsiaRF, we are pioneering this shift through the strategic synergy between HaLowFly (our Wi-Fi HaLow USB module) and OpenClaw.ai.
Imagine managing an industrial site spanning several kilometers. Instead of navigating a complex, high-latency cloud dashboard, you simply query your on-site gateway: “Analyze the vibration data from the east turbine and report any anomalies.” The OpenClaw AI agent processes this command locally, synthesizes the sensor data, and delivers a report through the robust, 1km+ long-range link provided by HaLowFly. This is the Intelligent Edge in action:
We are not just connecting devices; we are building an autonomous, private AIoT ecosystem where hardware doesn’t just transmit data—it understands it.
Let’s build a smarter, more private future together.
Sincerely,
CEO of AsiaRF
Outdoor autonomous systems require more than just accurate positioning, especially in mission-critical environments. In UAVs, defense applications and remote infrastructure systems, GNSS must continue operating under interference, degraded signals and dynamic conditions, while providing high data confidence.
The Septentrio mosaic-X5 GNSS M.2 receiver module is designed for this class of problem. It combines multi-frequency GNSS tracking with interference mitigation, signal authentication and integrity monitoring. When integrated with Gateworks industrial single board computers, it enables a modular architecture for high-integrity positioning at the edge.
The mosaic-X5 is a multi-band, multi-constellation receiver tracking GPS, Galileo, GLONASS, BeiDou and NavIC across multiple frequency bands. Multi-frequency operation improves positioning robustness and reduces susceptibility to ionospheric errors and signal degradation. It supports RTK positioning and update rates up to 100 Hz, allowing it to maintain low-latency tracking for dynamic systems such as UAVs and mobile platforms. These characteristics are essential for maintaining control fidelity in real-world environments.
For defense and mission-critical systems, the key question is not just “how accurate is the position?” but “can the system trust it?”
The mosaic-X5 integrates Septentrio’s AIM+ (Advanced Interference Mitigation) technology, which actively detects and suppresses interference across both narrowband and wideband signals. This includes resilience against pulsed and complex jamming scenarios.
It also incorporates:
These capabilities position the mosaic-X5 within the broader concept of assured PNT, maintaining reliable and trustworthy positioning in contested environments.
High-precision positioning depends on correction data. The mosaic-X5 supports standard methods such as NTRIP as well as satellite-delivered corrections.
Services like u-blox PointPerfect GNSS correction service provide PPP-RTK corrections over IP or L-band, enabling centimeter-level positioning without requiring local base stations. This model simplifies deployment for distributed systems and mobile fleets.
For example:
This flexibility allows system designers to align correction strategies with operational constraints.
Unmanned and defense systems operate in environments where GNSS degradation is expected, not exceptional. Positioning systems must maintain accuracy, continuity and integrity under these conditions. The GW16160 Mosaic x5 M.2 is industrial grade and engineered to perform in -40°C to +85°C temperatures and extreme environments.
The mosaic-X5 supports:
It is also included in the Blue UAS Framework, a program led by the U.S. Department of Defense to identify trusted components for unmanned systems. This reflects both technical capability and supply chain trust, two critical requirements for defense deployments.
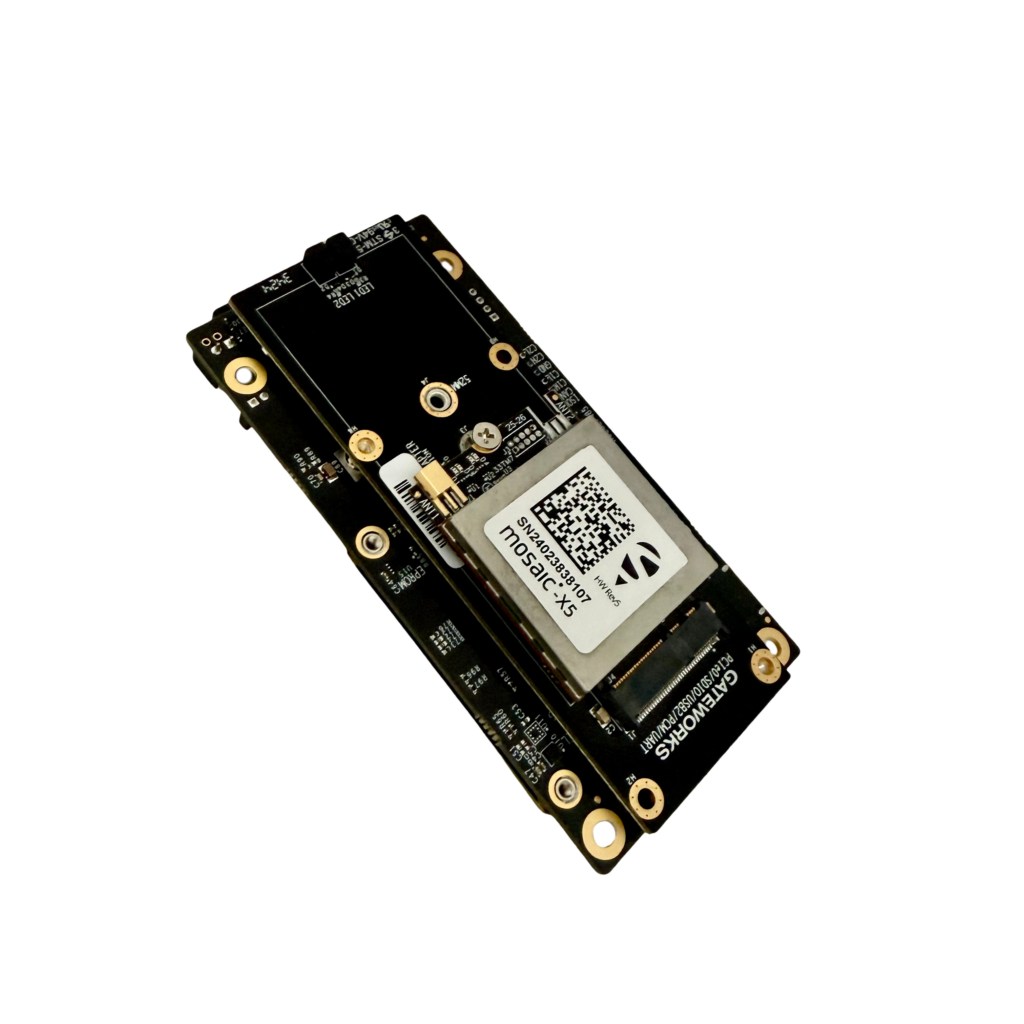
The Gateworks GW16160 GNSS M.2 module integrates the mosaic-X5 into a compact, deployable form factor. It provides a plug-and-play GNSS solution for Gateworks SBCs using a standard M.2 interface.
This reduces:
GW16160 pictured with the GW8100 VeniceFLEX
The GW16160 is for use in autonomous systems, robotics, drones and outdoor asset tracking, where reliable GNSS is a foundational capability.
Gateworks platforms provide the compute and connectivity layer:
The NXP i.MX95 application processor enables AI-accelerated processing, advanced security and real-time system integration, supporting GNSS as one component within a broader autonomy stack.
For defense and infrastructure deployments, hardware selection includes more than performance; it includes traceability, security and lifecycle control.
We design and manufacture all of our products in the United States, with a vertically integrated production process that emphasizes:
Gateworks products are assembled, tested and tracked within a single facility, with serialized components and real-time process visibility. These factors support deployments where supply chain transparency and long-term support are required. https://www.gateworks.com/company/manufacturing/
In practice, GNSS is one part of a larger system:
This modular architecture allows systems to scale across deployment environments while maintaining positioning performance and system flexibility.
For mission-critical outdoor systems, GNSS must deliver more than accuracy; it must deliver resilience, integrity and trust.
The mosaic-X5 addresses these requirements through multi-frequency tracking, interference mitigation, anti-spoofing and integrity monitoring. Gateworks single board computers combined with the GW16160 module allow for a practical path to deploying high-integrity positioning within embedded edge systems.
This approach aligns with the needs of modern autonomous and defense systems, where positioning is not just an input but a trusted foundation for decision-making.
Qualcomm’s engineering journey to evolve RF exposure management for modern wireless performance
When Qualcomm Technologies pioneered a new way to manage RF exposure through real-time averaging, it wasn’t simply about a new product. Behind this breakthrough development is a story about years of vision, collaboration and technical rigor that paved the way for a new era in RF exposure management. Spanning nearly a decade, the journey to develop this new technology — Time-Averaged Specific Absorption Rate (SAR), also known as TAS — stands as another example of our relentless drive to develop the best wireless experience possible and deliver maximum benefit to industry and consumers.
Developing TAS required years of systematic effort to redefine how wireless devices manage RF exposure. Our expertise in mobile gave us a unique line of sight to where the industry was headed, and we were pursuing novel ways to enable the growth required for better uplink performance.
The seeds of TAS were planted in 2012, when our engineers and scientists recognized a looming challenge: Legacy RF exposure management was holding back the promise of next-generation wireless technologies. The team saw that RF exposure management using static, capped peak power limits were stifling innovation and making it harder for device makers to deliver the performance users were demanding. Thus began a decade of dialog, research, testing and validation, culminating in a breakthrough solution that set a new standard for the industry.
This effort unfolded through several key milestones:
In 2012, we presented the concept of real-time averaging for RF exposure management to the FCC, initiating a dialogue that would shape future compliance procedures. We worked closely with regulators worldwide, advocating for the adoption of time averaging as a scientifically sound and practical approach to Regulatory compliance.
Between 2013 and 2015, Qualcomm Technologies developed and tested prototype algorithms and devices, including the first sub-6 GHz hand-held device. These efforts demonstrated the feasibility of real-time power averaging and provided critical data for regulatory review.
In 2016, we released to the regulators the first version of SAR measurement procedures for validating TAS algorithms. Since then, the test cases and procedures for regulatory certification of wireless devices enabled with TAS RF exposure management have been updated to validate enhancements and used to enable other TAS providers to enter the market.
As wireless technology has evolved, so have Qualcomm Technologies’ solutions. In 2018, our engineers expanded the algorithms to support 5G mmWave, addressing new challenges in device complexity and simultaneous multi-radio transmissions.
To ensure robust validation, Qualcomm Technologies partnered with leading compliance labs and third-party test houses worldwide. These collaborations helped to harmonize TAS testing procedures and meet the compliance test and regulatory certification needs of OEMs for on-time launch of their commercial products.
In 2018, the FCC first approved time averaging procedures for sub-6 GHz and mmWave devices, a direct result of our sustained engagement and technical advocacy. This enabled OEMs to design for compliance using time averaging, rather than relying on legacy power back-off methods.
Qualcomm invested significant resources in educating OEMs, operators, and labs about the new approach. Our teams provide training, consulting and technical support to accelerate industry adoption and ensure consistent, reliable compliance. To date, we have on-boarded 25 compliance labs in 8 different countries with 10 more labs in progress.
In April 2019, Qualcomm Technologies launched TAS as a commercial product, branded Smart Transmit, as an optional feature in the first 5G-enabled smartphones. Smart Transmit was more than a product introduction; it was the culmination of years of hard work, technical excellence and industry-wide collaboration. The technology was validated, the ecosystem was ready and the industry was aligned on the benefits of dynamic RF exposure management.
In addition to cellular, today Smart Transmit includes Wi-Fi, Bluetooth® wireless technology, UWB, RFID and satellite radios. The rise of AI, XR and an ever-increasing number of wearables are placing even more importance on the efficiency and capacity of uplink transmission as devices send more and more data to the cloud for real-time learning and personalization.
The principles and methodologies developed during this journey paved the way for other OEMs and set new benchmarks for compliance and performance. The groundwork laid between 2012 and 2019 enabled not just a technical solution, but a transformation in how the industry approaches RF exposure compliance and device performance.
Qualcomm’s leadership in developing TAS reflects the strength of our research and development teams, our engineering ingenuity and our commitment to solving the hardest problems in wireless.
The core mission of electronic warfare (EW) hasn’t changed: control the all communications so your forces can operate, and your adversary cannot. What has changed is everything around it. Today’s EW systems operate across airborne, naval and ground platforms that are increasingly built around multifunction RF architectures, where radar, sensing and electronic support capabilities are integrated into a single system.
In addition, performance expectations continue to rise. As threats appear without warning and signals shift instantly, response time is no longer measured in seconds, but in microseconds. Systems must continuously sense, interpret and respond across the entire RF spectrum.
EW environments now require wide instantaneous bandwidth, high output power and stable operation under extreme conditions. Publicly acknowledged frequency ranges such as 6–18 GHz and 32–38 GHz highlight the breadth of spectrum these systems must cover, often extending even further in practice.
Wideband EW design comes with distinct design challenges because of the need to make one RF chain behave well everywhere, all at once, across frequency, power levels and operating conditions.
EW receivers are designed to achieve high spurious-free dynamic range (SFDR), typically in the 90–110 dB range, enabling detection of weak signals in the presence of strong interferers. For example, a 6–18 GHz receiver with 500 MHz bandwidth and a ~5 dB noise figure yields a noise floor near −82 dBm, with minimum detectable signals around −72 dBm when accounting for detection margin. To meet these requirements, wideband low-noise amplifiers must maintain 2–3 dB Noise Figures with minimal Gain variation, while also delivering high linearity, often with Third-order Intercept Points near +30 dBm and compression points around +20 dBm, requiring careful matching, biasing and thermal design.
Here are the core challenges engineers must solve:
Maintaining Gain flatness across frequency is a key challenge in wideband EW design. Amplifiers inherently exhibit Gain variation over frequency, which becomes more pronounced as bandwidth increases, leading to uneven signal response and potential distortion. Addressing this requires carefully engineered matching networks and equalization techniques to stabilize performance across the operating range. In EW systems, inconsistent Gain can degrade signal fidelity, resulting in missed detections or reduced jamming effectiveness.
Maintaining linearity over wide bandwidths is another critical challenge in EW system design. Wideband signals often contain multiple simultaneous tones and complex modulations, increasing the likelihood of nonlinear behavior in RF components. This nonlinearity generates intermodulation distortion (IMD) and spectral regrowth, which can degrade overall system performance. In practice, distortion can mask weak signals, reduce the effectiveness of jamming operations and even interfere with friendly systems operating within the same spectral environment.
Balancing efficiency and bandwidth is a fundamental tradeoff in EW system design. High efficiency is typically easier to achieve in narrowband architectures, where components can be optimized for a specific frequency range. In contrast, wideband systems often sacrifice efficiency to maintain performance across a broader spectrum. This reduced efficiency leads to increased heat generation, larger power supply requirements and degraded size, weight and power (SWaP) performance, factors that directly impact system integration and operational effectiveness.
Maintaining consistent output power across a wide frequency range is a significant challenge in EW system design. As frequency increases, device performance often begins to degrade, making it difficult to sustain high power levels across the entire operating band. This variability can impact overall system effectiveness, particularly in jamming applications where consistent power delivery across the spectrum is essential to ensure reliable threat suppression.

Wideband EW architectures address core RF design challenges through a combination of solid-state technologies, optimized circuit design and system-level integration. Solid-state power amplifiers and carefully engineered RF front ends enable more predictable gain behavior across wide frequency ranges, while optimized matching networks and equalization techniques help minimize variation and ensure uniform signal amplification, which reduces the risk of missed detections or degraded jamming effectiveness. The inherent predictability of these devices also supports improved linearity, and when paired with optimized biasing and system-level design, helps reduce intermodulation distortion and spectral regrowth to preserve signal integrity in dense, multi-signal environments.
At the same time, solid-state solutions help manage the tradeoffs between efficiency and bandwidth by delivering improved Power-Added Efficiency (PAE) and more consistent performance across temperature and load conditions, reducing excess heat and supporting more SWaP-efficient designs. These architectures also enable more consistent output power across wide frequency ranges, particularly when implemented in modular form factors that allow power scaling without redesigning the entire transmit chain. On the receive side, wideband low-noise amplifiers and front-end limiters protect sensitive components while maintaining stable noise figure and gain, preserving detection capability across the spectrum. Finally, integrated RF modules simplify system design, reduce assembly complexity and improve repeatability, while the inherent reliability of solid-state architectures ensures consistent performance under sustained, mission-critical operating conditions.
Wideband EW design is a constant balancing act—maintaining gain, linearity, efficiency and stability across a broad and dynamic spectrum, often under high power and real-time operational constraints.
By aligning device technology, integration strategy and system design with the realities of wideband operation, engineers can overcome the core challenges of modern EW, and deliver predictable, high-performance capability across the electromagnetic spectrum.
For more information about our RF solutions for wideband, high-power systems, visit our EW solutions page. Additionally, you can find more interesting collateral on this subject by visiting our Qorvo Design Hub for a rich assortment of videos, technical articles, white papers, tools and more. For technical support, please visit Qorvo.com or reach out to Technical Support.
As demand for AI and digital services accelerates, the responsibility to grow sustainably has never been greater. This Earth Day reminds us that in technology, efficiency matters as much as innovation—and sustainability must be built into every design choice we make.
When we talk about improving Personal Computer (PC) energy efficiency, Intel approaches it as a three-layer challenge—starting at the platform and silicon architecture, extending through system level tuning, and reinforced by software level insight and optimization. This matters because meaningful energy savings don’t come from a single feature or setting; they come from aligning how hardware is designed, how systems behave in real world use, and how software interacts with the platform over time. Intel’s focus is on reducing energy use during everyday operation—the phase of a PC’s lifecycle where users and IT teams have the greatest opportunity to lower power consumption while still getting the performance and AI enabled experiences they expect.
At the platform level, the latest Intel® Core™ Ultra Series 3 processors are designed with energy efficiency as a foundational architectural goal. These platforms improve performance per watt by tightly integrating compute, graphics, memory, and dedicated engines for specific workloads, allowing common tasks—and select AI workloads—to run in more energy‑efficient states rather than relying solely on high‑power CPU cores. This architectural approach helps scale energy use to actual demand, reducing wasted power during idle and light‑use scenarios while preserving responsive performance when workloads intensify.
That foundation is strengthened at the system and software layers, where intelligent tuning and clear visibility enable smarter, more efficient operations. At the system level, Intel® Dynamic Tuning Technology uses advanced AI‑ and machine‑learning–based algorithms, combined with real‑time telemetry, to dynamically adjust power and thermal behavior based on workload demand—helping balance performance, acoustics, and energy use without manual intervention. At the software level, the Intel® Battery Life Diagnostic Tool provides visibility into how applications, background processes, and system configurations affect a PC’s ability to reach low‑power states, including identifying software behaviors that limit efficiency. Together, Intel® Core™ Ultra architecture, Intel® Dynamic Tuning Technology, and the Intel® Battery Life Diagnostic Tool demonstrate an end‑to‑end approach to energy efficiency: design for efficient execution in silicon, optimize behavior intelligently at the system level, and continuously improve through software insight—ensuring efficiency gains show up in real‑world use.
When you send an email, stream a video, or use AI-powered apps, you’re connected to data centers. Intel’s commitment to sustainability means those experiences are powered by technology designed to be energy-efficient and environmentally responsible. Energy efficiency is the ultimate competitive advantage in the AI era, and Intel is committed to leading the way toward sustainable, high-performance data centers for a sustainable future.
Our approach to power more energy-efficient and cost-effective data centers is structured around four key layers, spanning the entire product lifecycle from design to data center operations:
Our impact is reflected in how these solutions are being deployed around the world. Intel® Xeon® 6 processors can deliver up to an 80% reduction2 in power consumption for AI image classification workloads compared to older generations, helping data centers do more with less energy. Server consolidation further lowers carbon footprint while reducing physical data center space. Through collaborations with Shell and Submer, Intel has helped enable the industry’s first certified immersion cooling solution for AI infrastructure. At the University of Waterloo, the Nibi supercomputer—powered by Intel Xeon 6 processors and liquid cooling—has become Canada’s first large‑scale immersion‑cooled supercomputer, supporting more than 4,000 researchers in a more sustainable way. And in hyperscale environments, Microsoft Azure uses Intel® Enhanced Latency Control to deploy more servers within existing data center footprints, improving performance per watt while reducing overall power consumption..
By designing energy‑efficient platforms that scale with the world’s needs, we’re helping ensure digital innovation advances responsibly. It reflects our commitment to progress with purpose: delivering the performance people rely on, while caring for the planet and the resources we all share.
Global Partnership to Power Next-Generation, High-Speed Connectivity for Future Kentucky Derby Experiences and Across CDI Properties
Louisville, KY., (April 15, 2026) – Cisco (Nasdaq: CSCO) and Churchill Downs Incorporated (“CDI” or “the Company”) (Nasdaq: CHDN) today announced a multi-year partnership to significantly enhance the networking capabilities at the historic Churchill Downs Racetrack (“Churchill Downs”). As the Official Enterprise Networking and Network Infrastructure Partner of the Kentucky Derby, Cisco’s industry-leading AI-ready secure networking platform and solutions will bring simplicity, visibility, reliability and protection across the organization’s expansive digital footprint.
This partnership represents a significant investment in the future of connectivity at Churchill Downs, designed to support next-generation fan experiences at future Kentucky Derby Weeks and other year-round events. The network refresh — spanning more than 7,000 switches and a modernized routing fabric — will deliver high-speed, high-capacity connectivity across all CDI properties built for performance at scale for one of the world’s largest sporting events.
With 12 regional casinos and 18 live and historical racing venues, CDI operates a large and complex network environment. By consolidating capabilities under Cisco Catalyst Center, the Company will enhance visibility, security and control while delivering faster, more reliable connectivity across all locations. Throughout the partnership, Cisco and CDI will continue to advance wireless and routing innovations to further strengthen speed, performance and digital resilience across the enterprise.
“This partnership with Cisco reflects our commitment to providing a world-class experience for our guests by modernizing and connecting our core technology platforms across networking, security, and observability,” said Nate Simon, Senior Vice President and Chief Technology Officer at CDI. “With Cisco’s technology, we will deliver faster, more connected experiences across our properties, while enhancing security and ensuring reliable operations — from everyday guest interactions to the scale of the Kentucky Derby.”
For the 350,000+ fans who attend the Kentucky Derby Week events each year, this network upgrade will ensure a seamless digital experience — from mobile ticketing and high-speed access to betting platforms like TwinSpires.com to the ability to share high-definition content in real-time. For Churchill Downs staff, the modernized infrastructure provides the reliable, high-speed connectivity required for point-of-sale systems to process food and beverage and wagering transactions without interruption, significantly reducing wait times and ensuring that operations run with the precision expected of the world’s most iconic horse race and cultural event.
“Racetracks like Churchill Downs don’t just require speed on the track — they demand it from their networks,” said Anurag Dhingra, SVP & GM, Enterprise Connectivity & Collaboration, Cisco. “Cisco’s networking technology delivers real-time, reliable connectivity that keeps every moment, from the grandstands to the winner’s circle, running flawlessly.”
CDI will leverage Cisco’s unified on-premises networking platform, powered by Catalyst Center, to centrally manage, secure and automate its enterprise network. With Catalyst Center, CDI can streamline operations through zero-touch provisioning, policy-based automation, and orchestrated rolling upgrades that help minimize disruption while maintaining reliable connectivity across its venues. Cisco Success Tracks will further support CDI with efficient asset tracking and proactive software management for secure, high-performing network operations. Use of Splunk Observability Cloud will ensure greater digital resiliency across the entire CDI digital environment, including the performance of TwinSpires and Churchill Downs application infrastructure throughout the year to deliver a seamless user experience, especially on peak days during Kentucky Derby Week.
For more than a decade, marquee sports teams, events, organizations and venues around the world have relied on Cisco technology and expertise, including McLaren Mastercard Formula 1 Team, Real Madrid F.C., United States Golf Association (USGA), Live Nation Entertainment, Madison Square Garden and many more.
About Churchill Downs Incorporated
Churchill Downs Incorporated (“CDI”) (Nasdaq: CHDN) has been creating extraordinary entertainment experiences for over 150 years, beginning with the company’s most iconic and enduring asset, the Kentucky Derby. Headquartered in Louisville, Kentucky, CDI has expanded through the acquisition, development, and operation of live and historical racing entertainment venues, the growth of online wagering businesses, and the acquisition, development, and operation of regional casino gaming properties. ChurchillDownsIncorporated.com
About Churchill Downs Racetrack
Churchill Downs Racetrack (“CDRT”), the world’s most legendary racetrack, has been the home of The Kentucky Derby, the longest continually held annual sporting event in the United States, since 1875. Located in Louisville, CDRT features a series of themed race days during Derby Week, including the Kentucky Oaks, and conducts Thoroughbred horse racing during three race meets in the Spring, September, and the Fall. CDRT is located on 175 acres and has a one-mile dirt track, a 7/8-mile turf track, a stabling area, and provides seating for approximately 60,000 guests. The stable area has barns sufficient to accommodate 1,400 horses and a 114-room dormitory for backstretch personnel. CDRT also has a year-round sports book and simulcast wagering facility. www.ChurchillDowns.com.
About the Kentucky Derby
The $5 million Kentucky Derby takes place on the first Saturday in May at historic Churchill Downs Racetrack in Louisville, Kentucky. Inaugurated in 1875, the legendary 1 1/4-mile race for 3-year-old Thoroughbreds is the longest continually held major sporting event in North America and the first leg of horse racing’s Triple Crown series. Also known as The Run for the Roses® and The Most Exciting Two Minutes in Sports®, the Kentucky Derby is the most attended horse race in the nation. The 152nd Kentucky Derby will take place on Saturday, May 2, 2026. KentuckyDerby.com
About Cisco Cisco (NASDAQ: CSCO) is the worldwide technology leader that is revolutionizing the way organizations connect and protect in the AI era. For more than 40 years, Cisco has securely connected the world. With its industry leading AI-powered solutions and services, Cisco enables its customers, partners and communities to unlock innovation, enhance productivity and strengthen digital resilience. With purpose at its core, Cisco remains committed to creating a more connected and inclusive future for all. Discover more on The Newsroom and follow us on X at @Cisco.
Cisco and the Cisco logo are trademarks or registered trademarks of Cisco and/or its affiliates in the U.S. and other countries. A listing of Cisco’s trademarks can be found at http://www.cisco.com/go/trademarks. Third-party trademarks mentioned are the property of their respective owners. The use of the word ‘partner’ does not imply a partnership relationship between Cisco and any other company.
Growth should feel like progress.
But for a lot of MSPs, there comes a point where growth starts to feel heavier instead. New clients are coming in, and revenue is rising, yet the day-to-day operation feels more stretched, not more efficient. The service desk is constantly busy. Senior techs keep getting pulled into escalations. The team is working harder just to maintain the same standard of delivery.
The usual response is to hire more people. On paper, it makes sense. More demand requires more capacity. In practice, it’s where margins start to plateau because hiring doesn’t fix the underlying problem, it just helps you keep up.
The linear model that breaks margins
Most MSPs experience demand in a simple, linear way: More clients mean more tickets, and more tickets require more staff. It feels logical because it reflects what the team sees every day: More endpoints, user issues, performance complaints, and security-related noise.
But the model only works for so long, and isn’t scalable.
Headcount is one of the most expensive and least flexible ways to increase capacity. It comes with recruiting pressure, onboarding time, management overhead, and ongoing labor costs. It also increases dependency on specific individuals, which creates real risk when key technicians leave, burn out, or simply become the bottleneck.
It’s the daily MSP leader balancing act: Protect service quality and keep clients happy, without letting labor costs eat margins.
The real constraint isn’t demand
The hard truth is that most service desks aren’t under pressure because of major incidents every day. They are under pressure because of volume. Small, repetitive (and often preventable) issues that fill the day and steadily drain capacity like:
This is operational noise, and it exists regardless of how many techs you hire.
When you hire more people, you increase your ability to process that noise, but you don’t reduce the amount of it. The same patterns keep creating the same work, and over time, you end up with a larger team handling the same problems at a higher cost.
Growth becomes less profitable because revenue rises, but the cost of delivering it rises right alongside it. Your margins don’t improve because the system underneath the business hasn’t changed.
The hidden cost is where your best people spend their time
As the linear model scales, your most capable people stop doing your most valuable work.
When senior staff are tied up in low-value investigations, constant escalation, and reactive firefighting, they are not improving the business. They’re being pulled away from the work they should be focused on, like standardizing service delivery, building repeatable processes, rolling out new security offerings, or creating operational improvements that increase margins over time.
The business keeps moving but it doesn’t move forward as it should, and it’s one of the clearest signs that the system is under strain. Your most experienced people are spending too much of their time protecting the present and not enough improving the future.
Reduce the work, scale well
The MSPs that scale most effectively don’t focus solely on adding capacity. Instead, they focus on reducing the effort required to deliver their services. That starts with prevention.
Every security event that reaches the helpdesk has already created work for the team. There is detection, alerting, triage, investigation, remediation, client communication, and the usual context switching that breaks a technician’s flow. Even if the event turns out to be harmless, the time has already been spent.
Across dozens or hundreds of clients, that creates a significant operational load. The earlier you stop the problem, you stop a significant amount of “noisy” work from ever appearing.
Prevention creates a quieter operation
If you can stop threats before a connection is made, a payload is downloaded, or an alert is generated, you remove the whole chain of downstream effort.
Fewer threats getting through means fewer alerts, fewer tickets, fewer investigations, and less need for senior escalation on routine security issues.
The impact is a quieter system that allows each technician to support more users and endpoints without constantly feeling stretched. It makes onboarding smoother because new clients don’t immediately feed unnecessary noise into the service desk. It gives the business a more predictable cost base and reduces the need to keep solving the same operational problems with more people.
Over time, it stabilizes your cost base. Instead of revenue and headcount rising together, you increase the number of clients each technician can support. Margin improves not because you charge more, but because it costs less to deliver the same service at the same (or higher) standard.
The advantage of provable value
When your security approach is preventative rather than reactive, the conversation with clients changes. You are no longer limited to showing how many tickets were closed or how quickly incidents were handled. You can show how much disruption and risk was avoided in the first place.
Value is easier to demonstrate because the outcome isn’t activity; it’s stability.
That creates a stronger foundation for pricing, packaging, and expanding security services.
Growth isn’t a bigger team, it’s a better system
Hiring more techs will always increase capacity in the short term.
But it will not, on its own, make your MSP more scalable. It will not reduce operational noise, simplify delivery, or lower the cost to support each client.
Only removing unnecessary work from the system does that. That is what separates growth from profitable growth. Not a bigger team, but a better operating model.
Learn how DNSFilter helps MSPs cut ticket volume, reduce technician workload, and improve margins at the DNS layer; start your free trial today.


